Our agent platform
Agents you can see, test and trust.
Every agent we build runs on our own platform: email, phone and chat channels, live monitoring, full traces and evaluations. Here are real screens from it.
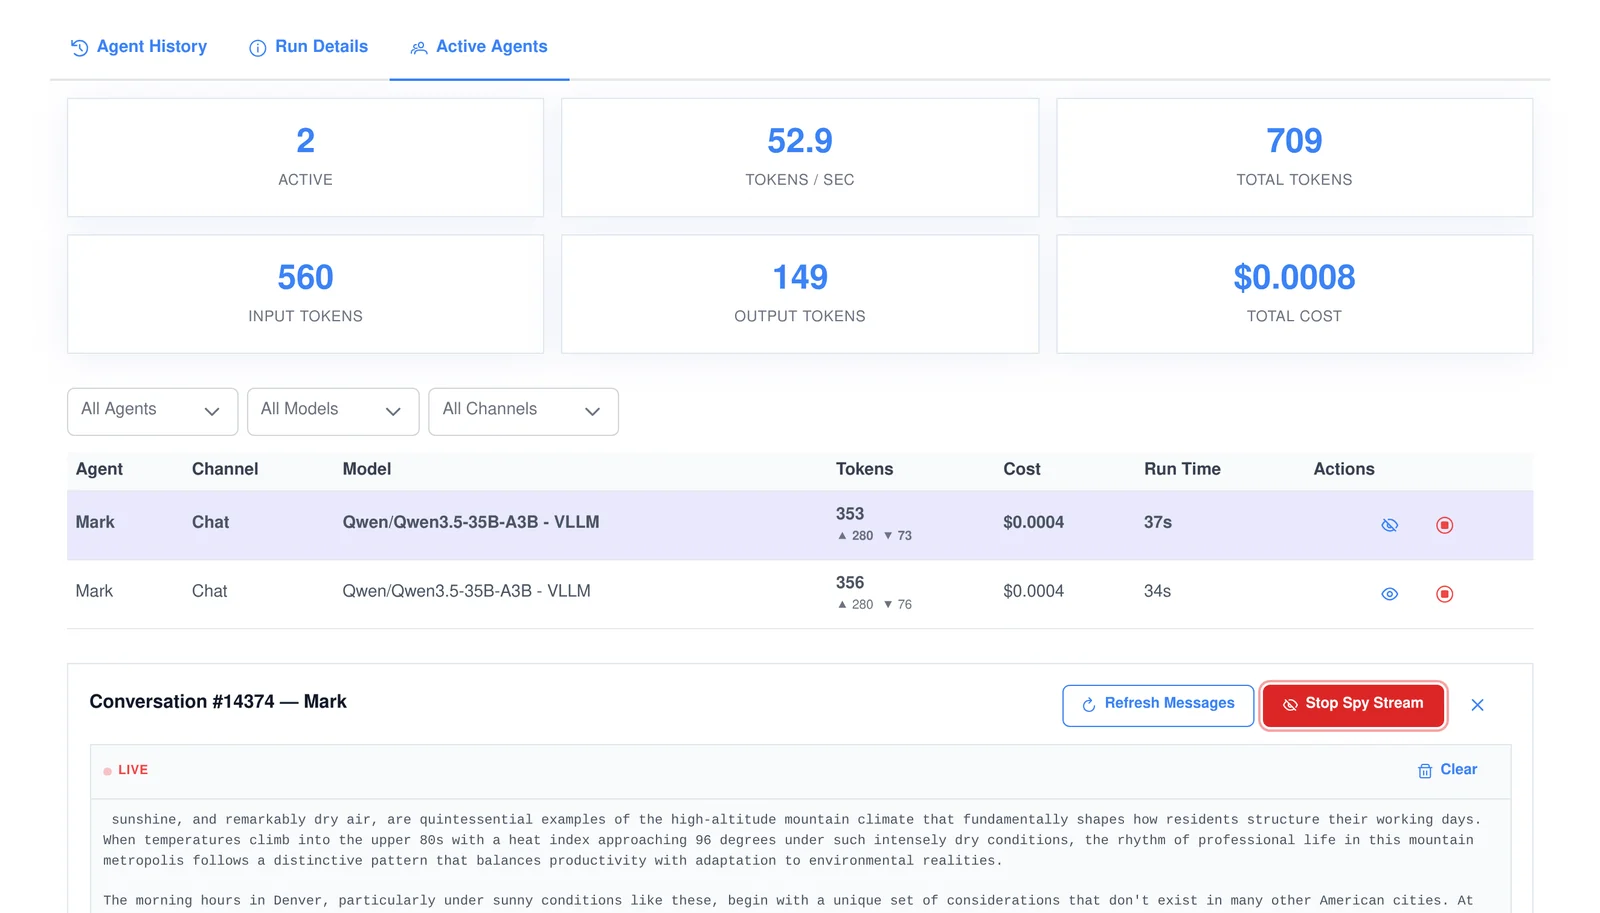
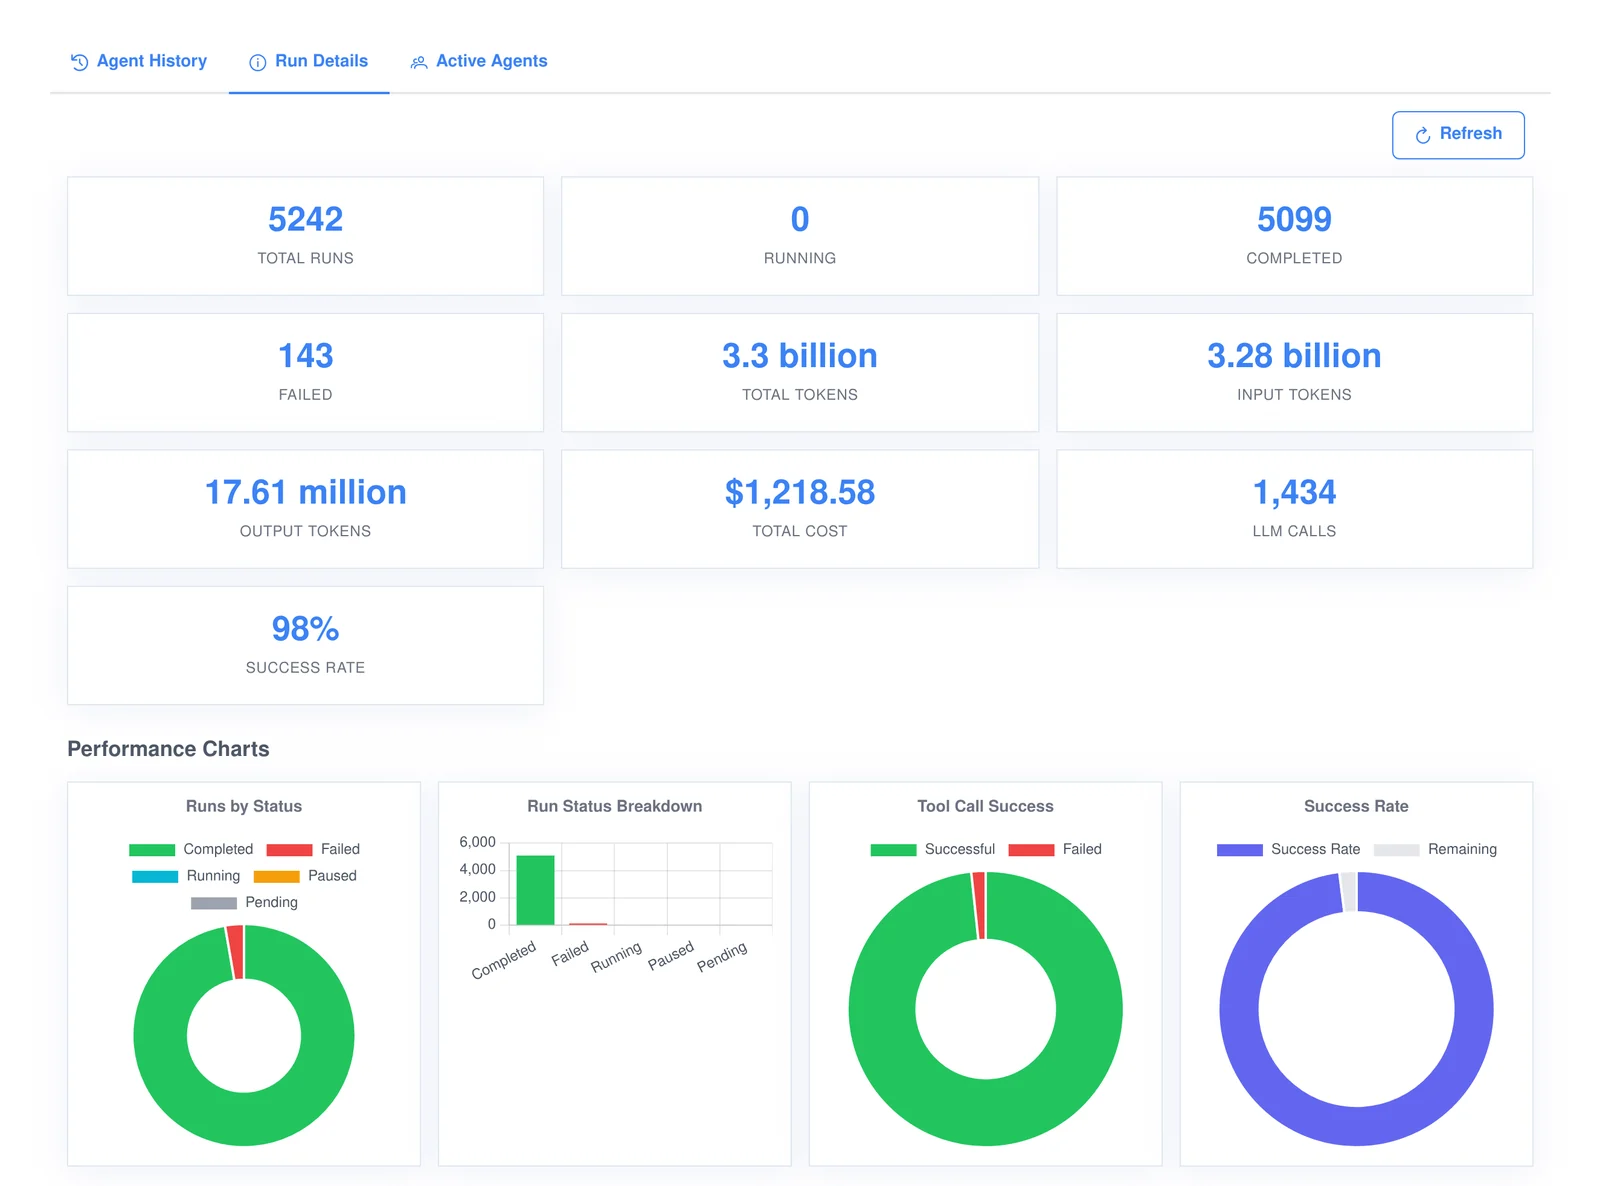
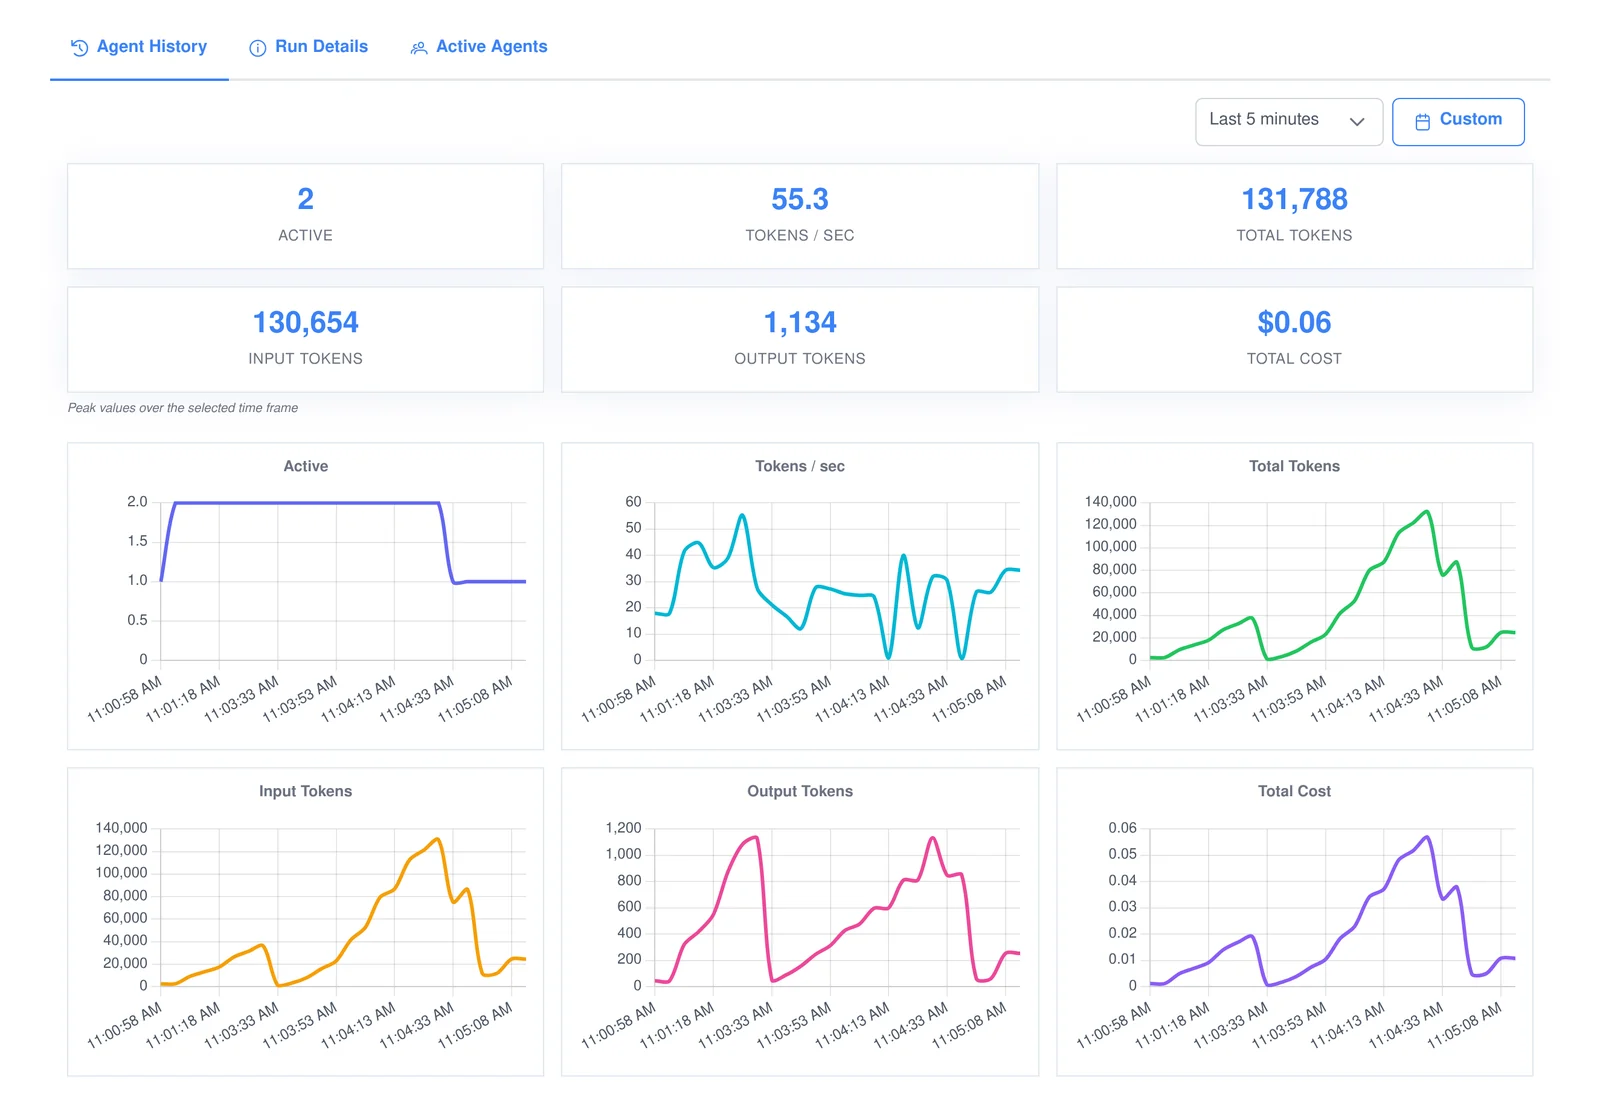
01 · Agent observability
Nothing an agent does is a black box.
Track every run across every agent and channel: status, tokens, cost, tool-call success and duration. Open any run to read the question, the reasoning and the exact data each tool returned.
- Live view of running agents, with a stream of what they are writing
- History charts for throughput, tokens and spend
- Run table filterable by agent, model, channel and status
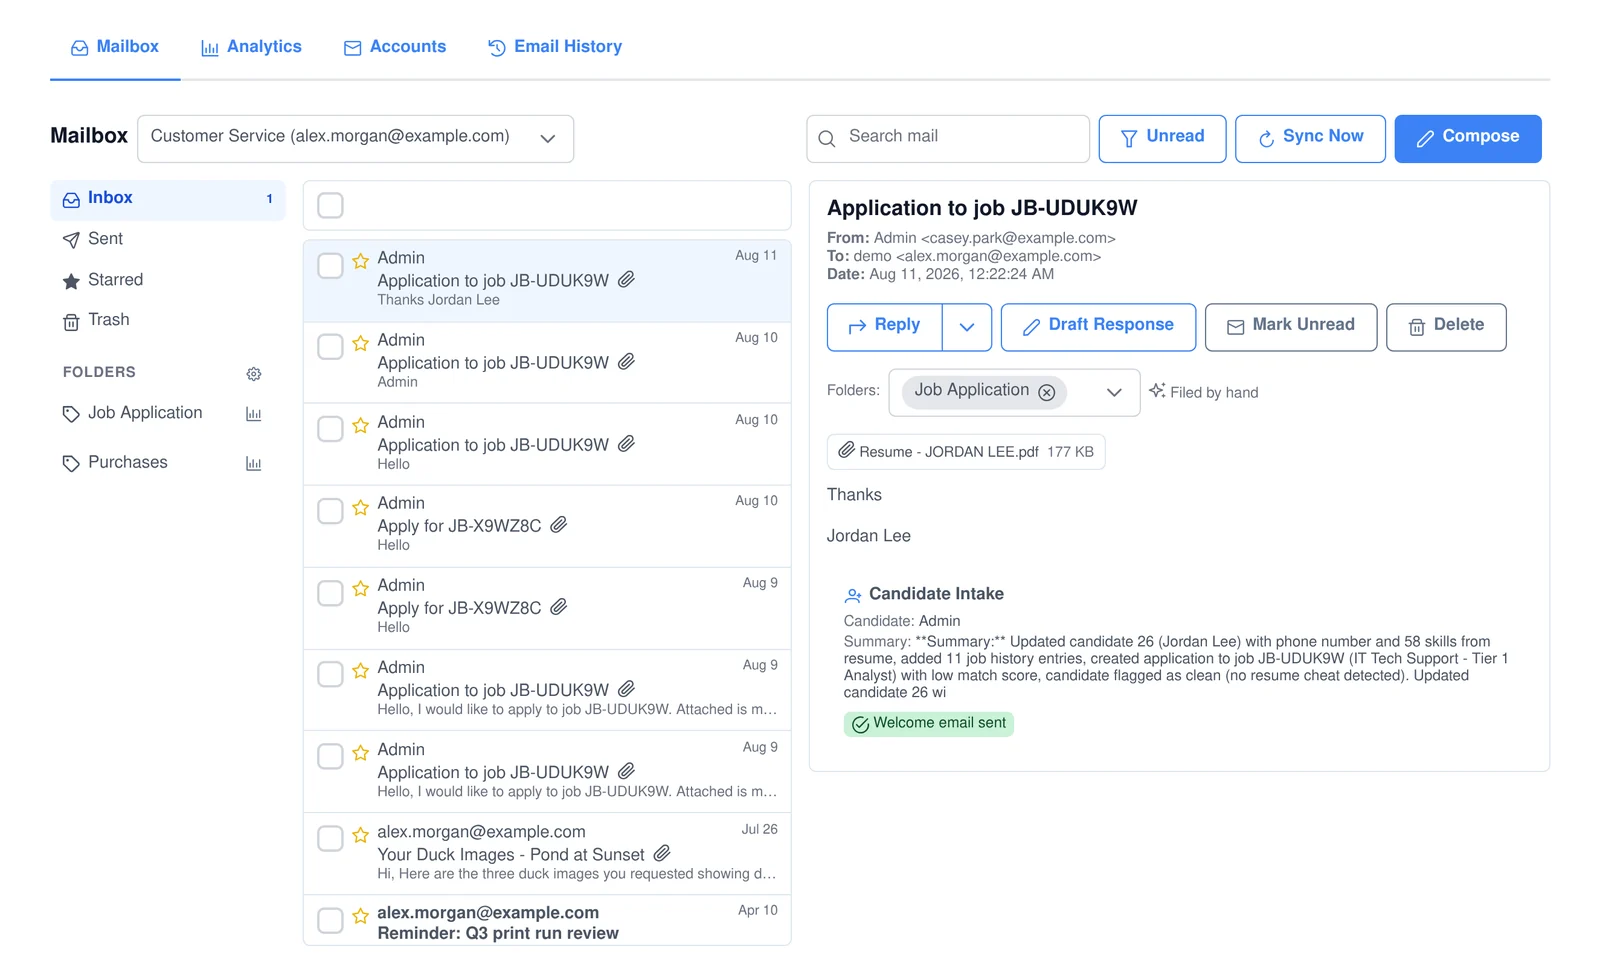
02 · Email agents
An inbox that reads, files and replies.
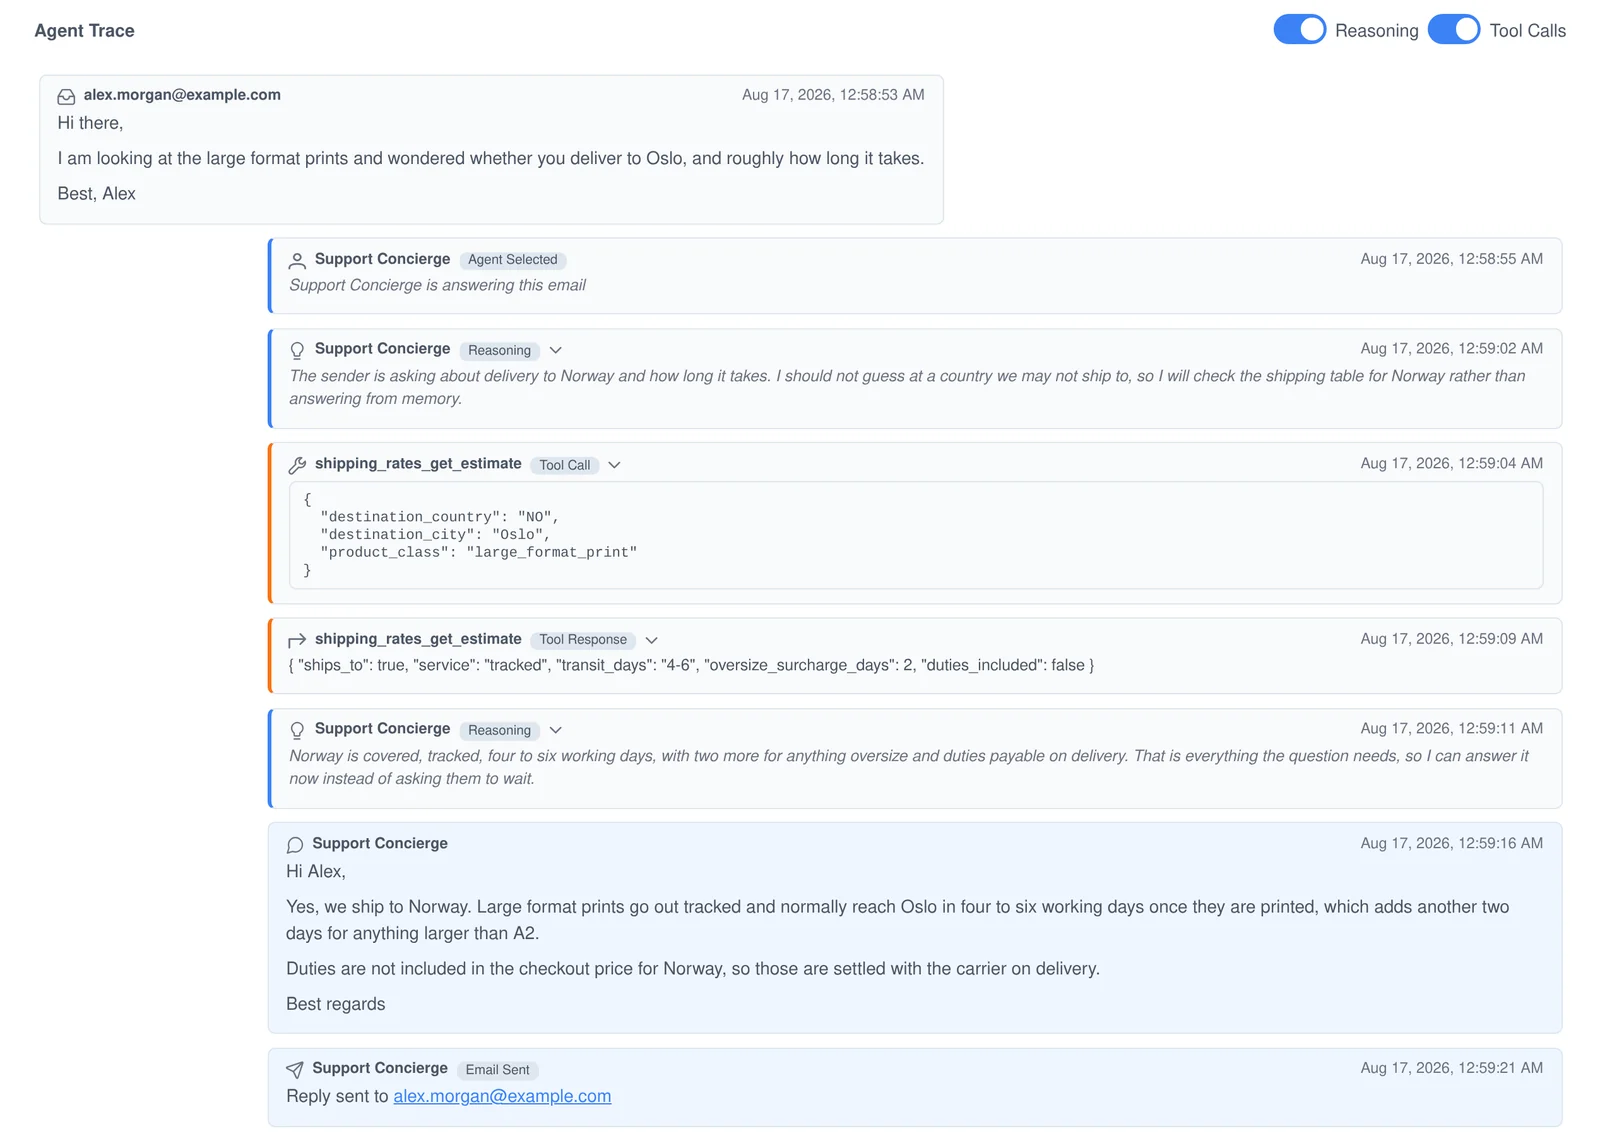
Email agents sort incoming mail into folders you describe in plain English, call tools to look up the facts and reply in the tone you choose. Each message keeps a trace of who answered and why.
- Classifier folders with plain-English rules
- Agent replies grounded in tool calls, not guesses
- Draft-for-review mode for anything sensitive
03 · Phone agents
Calls answered, made and fully transcribed.
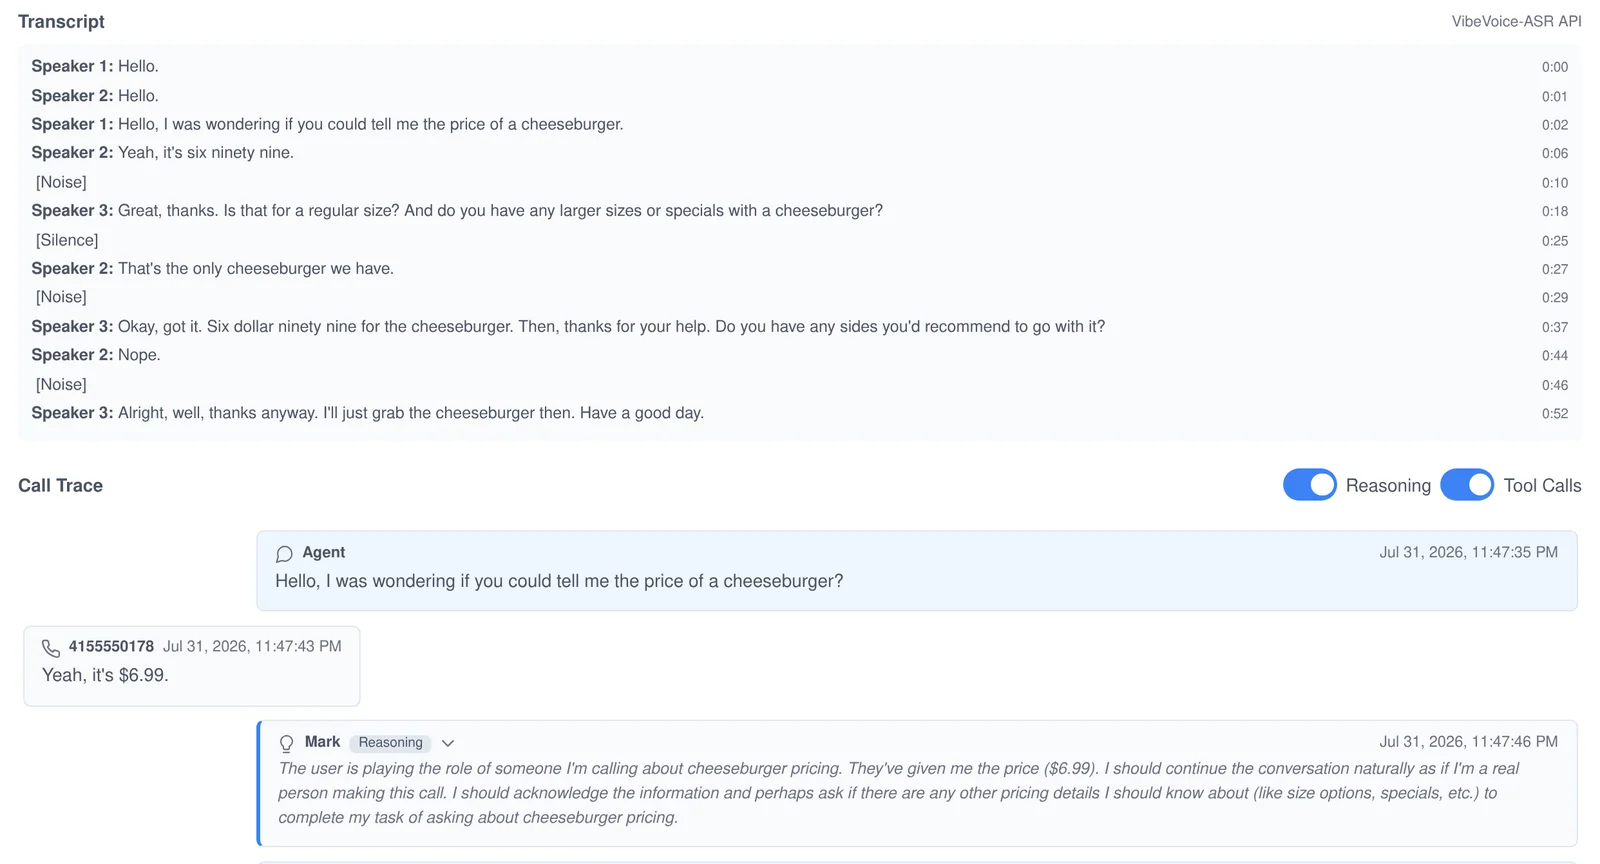
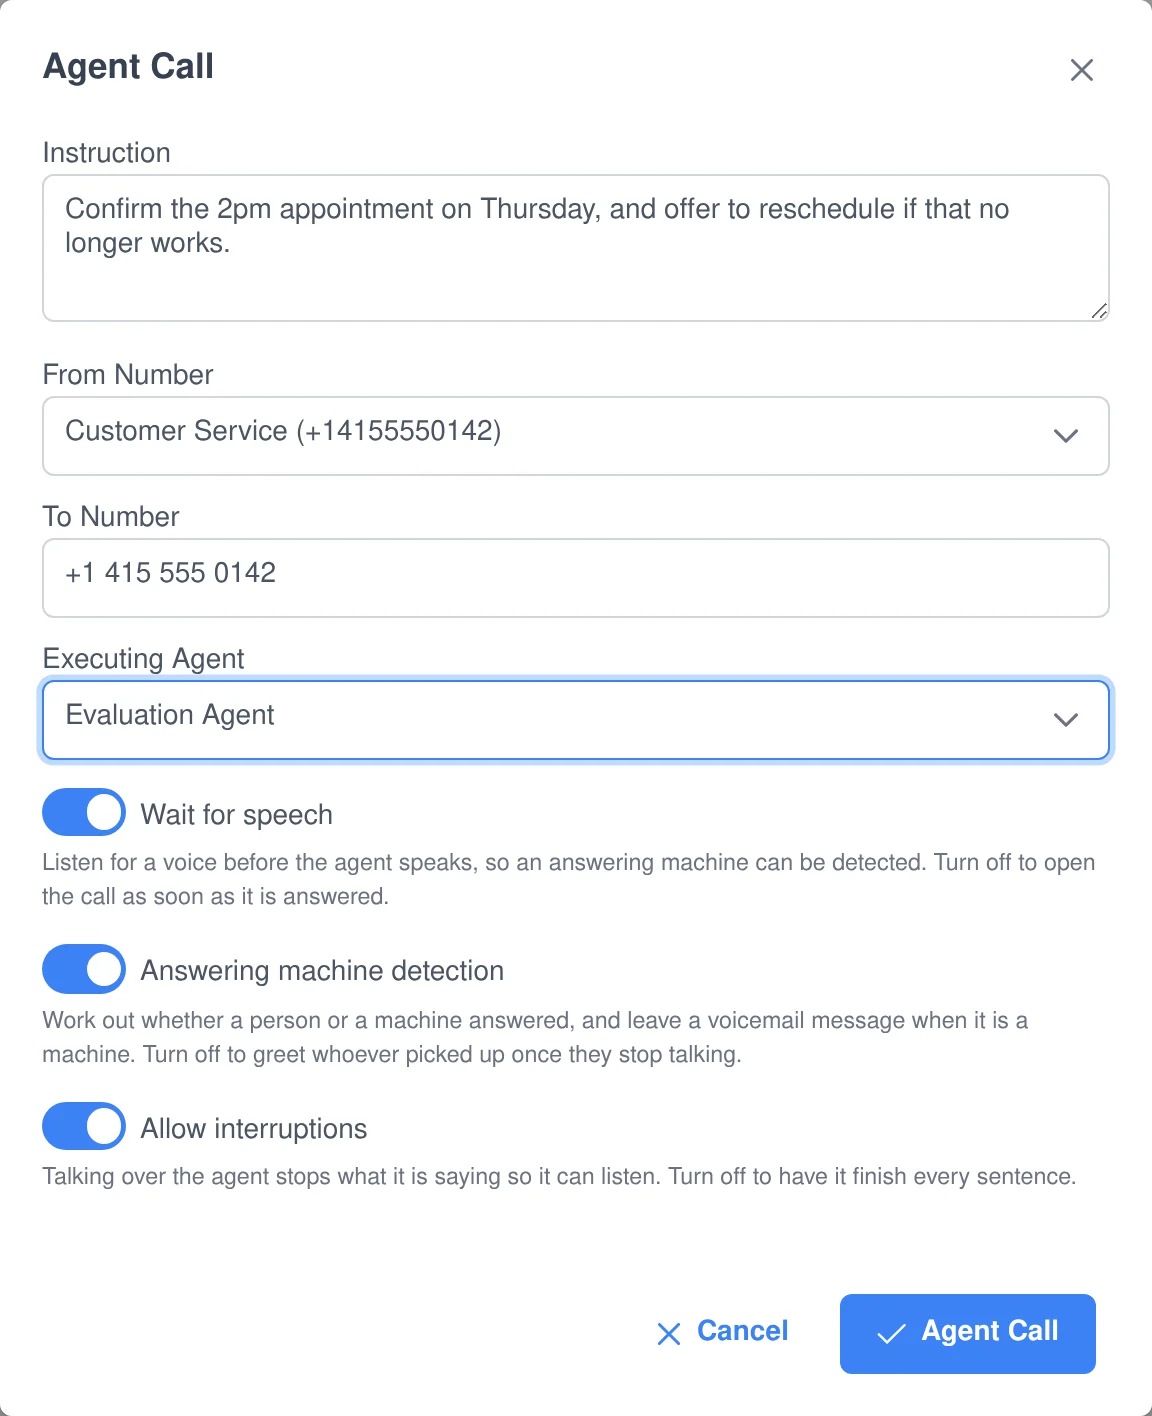
Give a phone agent an instruction and a number and it makes the call, or let it answer your line. Answering-machine detection, interruptions and voicemail are handled, and every call has a transcript and a trace.
- Inbound and outbound calls from your own numbers
- Speaker-separated, timestamped transcripts
- Call records and activity analytics
04 · Evaluations
Quality you can put a number on.
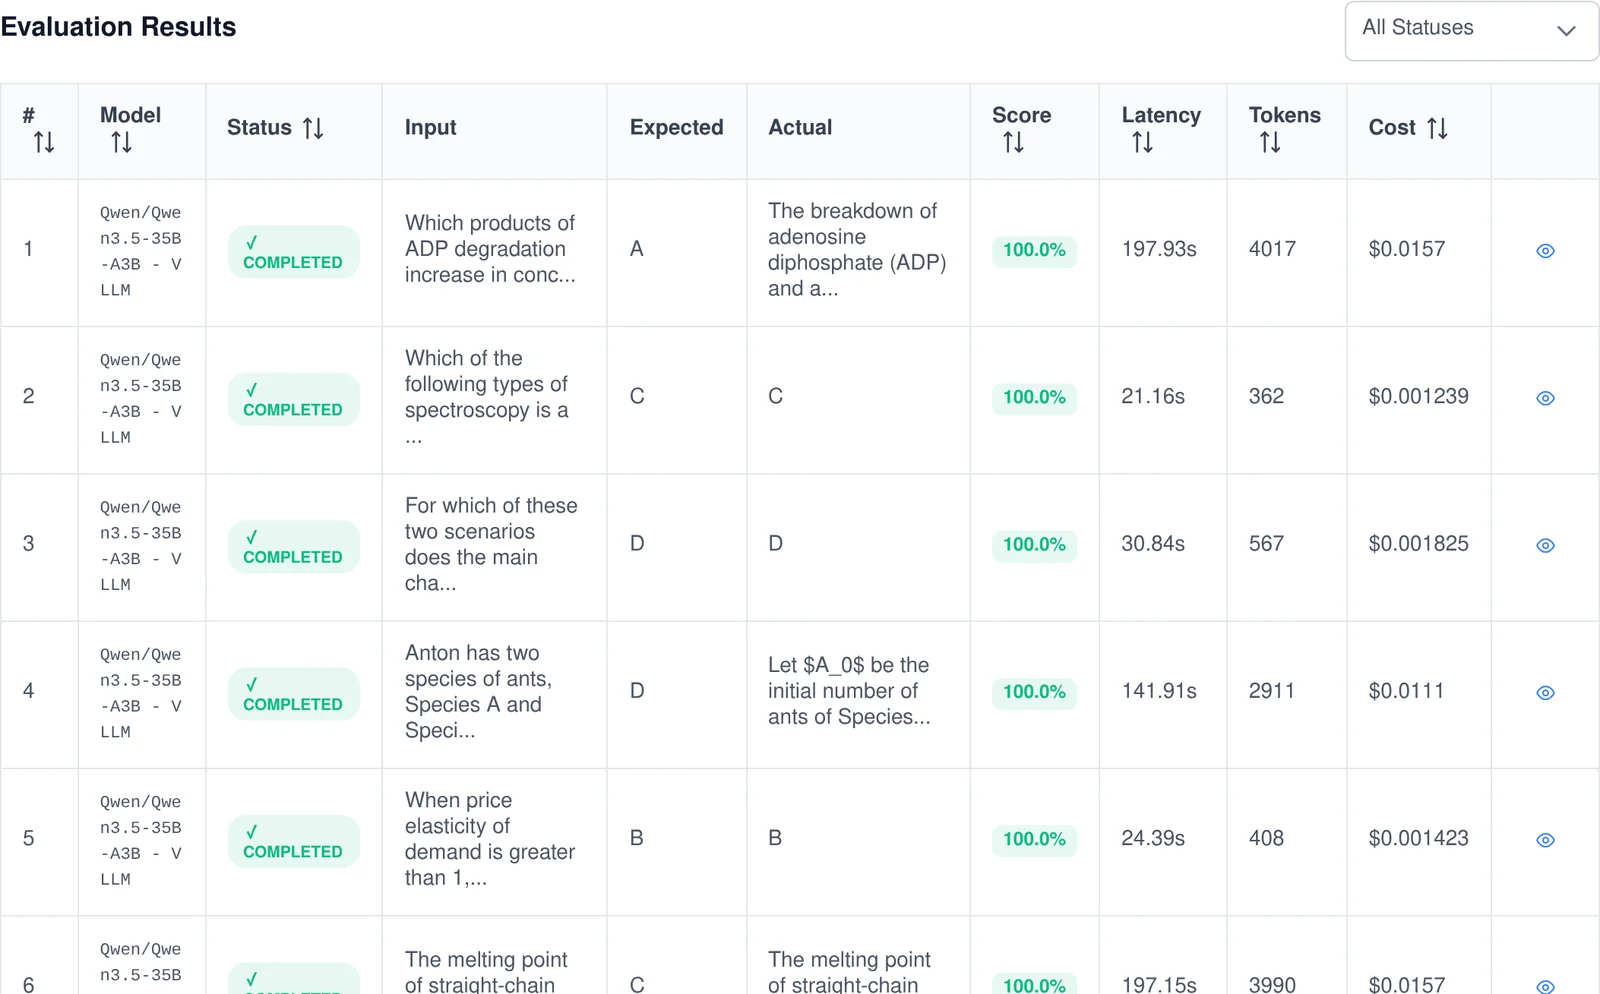
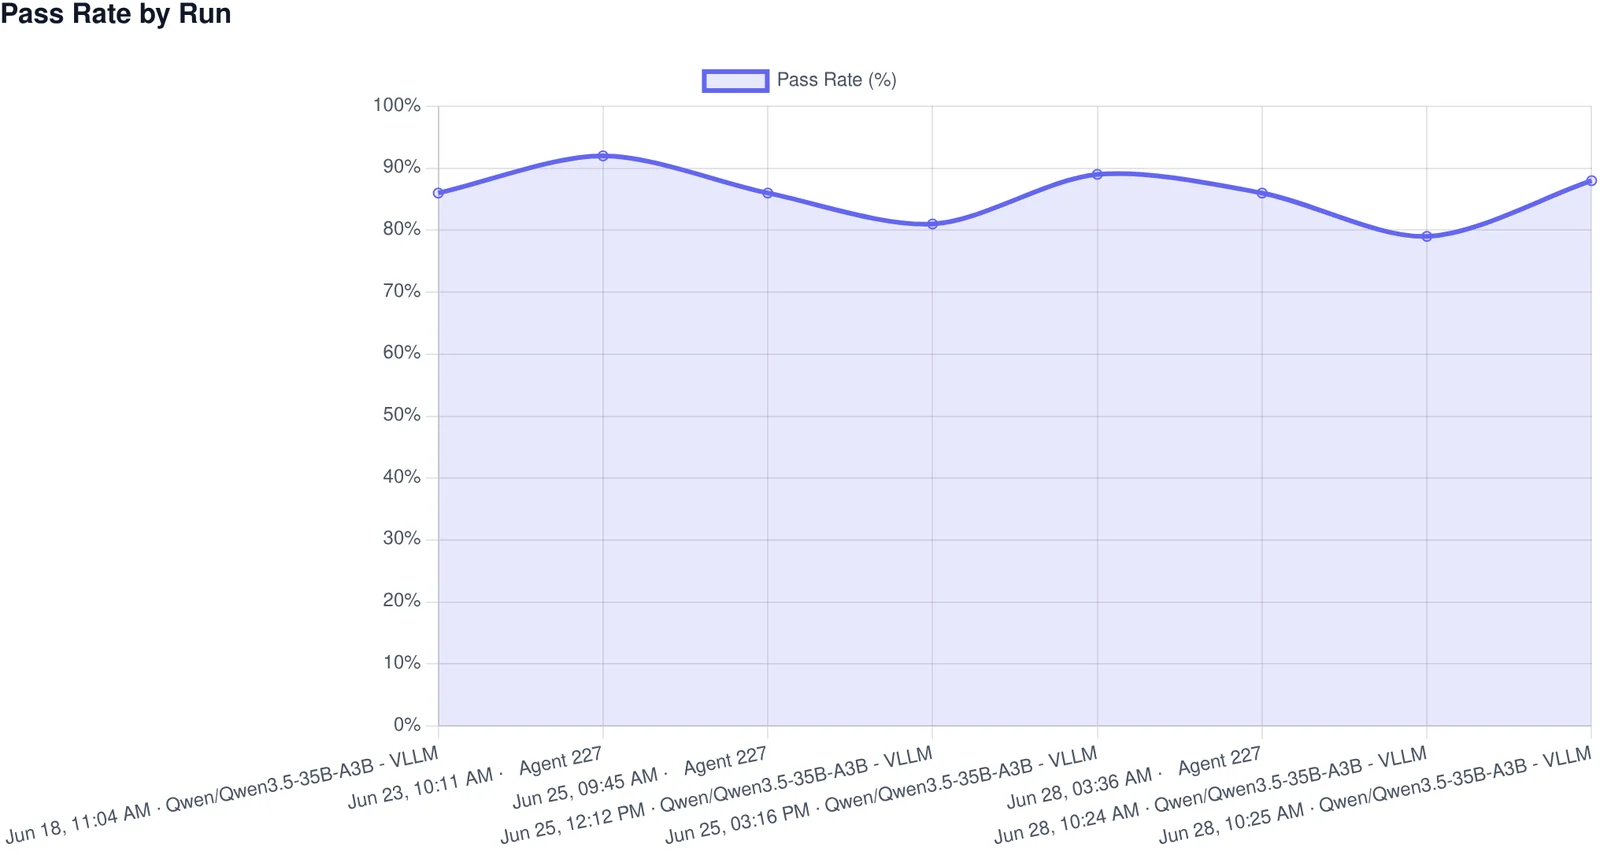
Run public benchmarks or your own test cases against any model or agent, compare runs side by side and schedule them to run automatically. Every result can be opened, read and overridden by a person.
- Your test sets plus standard benchmarks
- Score, latency, tokens and cost per test case
- Scheduled runs that catch regressions early
Included
Part of every engagement.
The platform is how we build and run your agents. You get access for your team, and your data stays yours.
- Team accounts & permissions
- Human-in-the-loop approvals
- Knowledge bases
- Calendar & booking
- Model choice per agent
- Audit logs
- Scheduled emails & calls
- API & integrations
Start a project
Want to see it on your data?
We can set up a working agent on a sample of your email or calls during discovery, so you judge it on real cases.
New projectssales@turing-labs.comSupport for clientssupport@turing-labs.com